Latin · custos — a guardian; the one who keeps
Intake, major incident command, self-healing and reporting as one system over one service model. The ticket is a side effect of the work, not the point of it — and the artificial intelligence sits where judgement is genuinely needed, never in the path where something executes.
Quis custodiet ipsos custodes?
Who will guard the guards themselves?
Juvenal, Satires VI
It is the oldest question in governance, and it is exactly the question a security reviewer asks the moment you tell them software will propose changes to production. Not can it fix things, but what stands between a suggestion and a command that runs.
The answer, in four parts
A custos was not the person who did the work. He was the one entrusted with the keys — who decided what passed and what did not, and answered for it afterwards. That is the part of this product that matters. The automation is ordinary; every vendor has some. The gate in front of it, and the evidence trail behind it, are what make it safe to point at a production estate.
Every screenshot below is the running product, captured from the demo environment you can open in the next thirty seconds. Nothing here is a mockup.
The gate
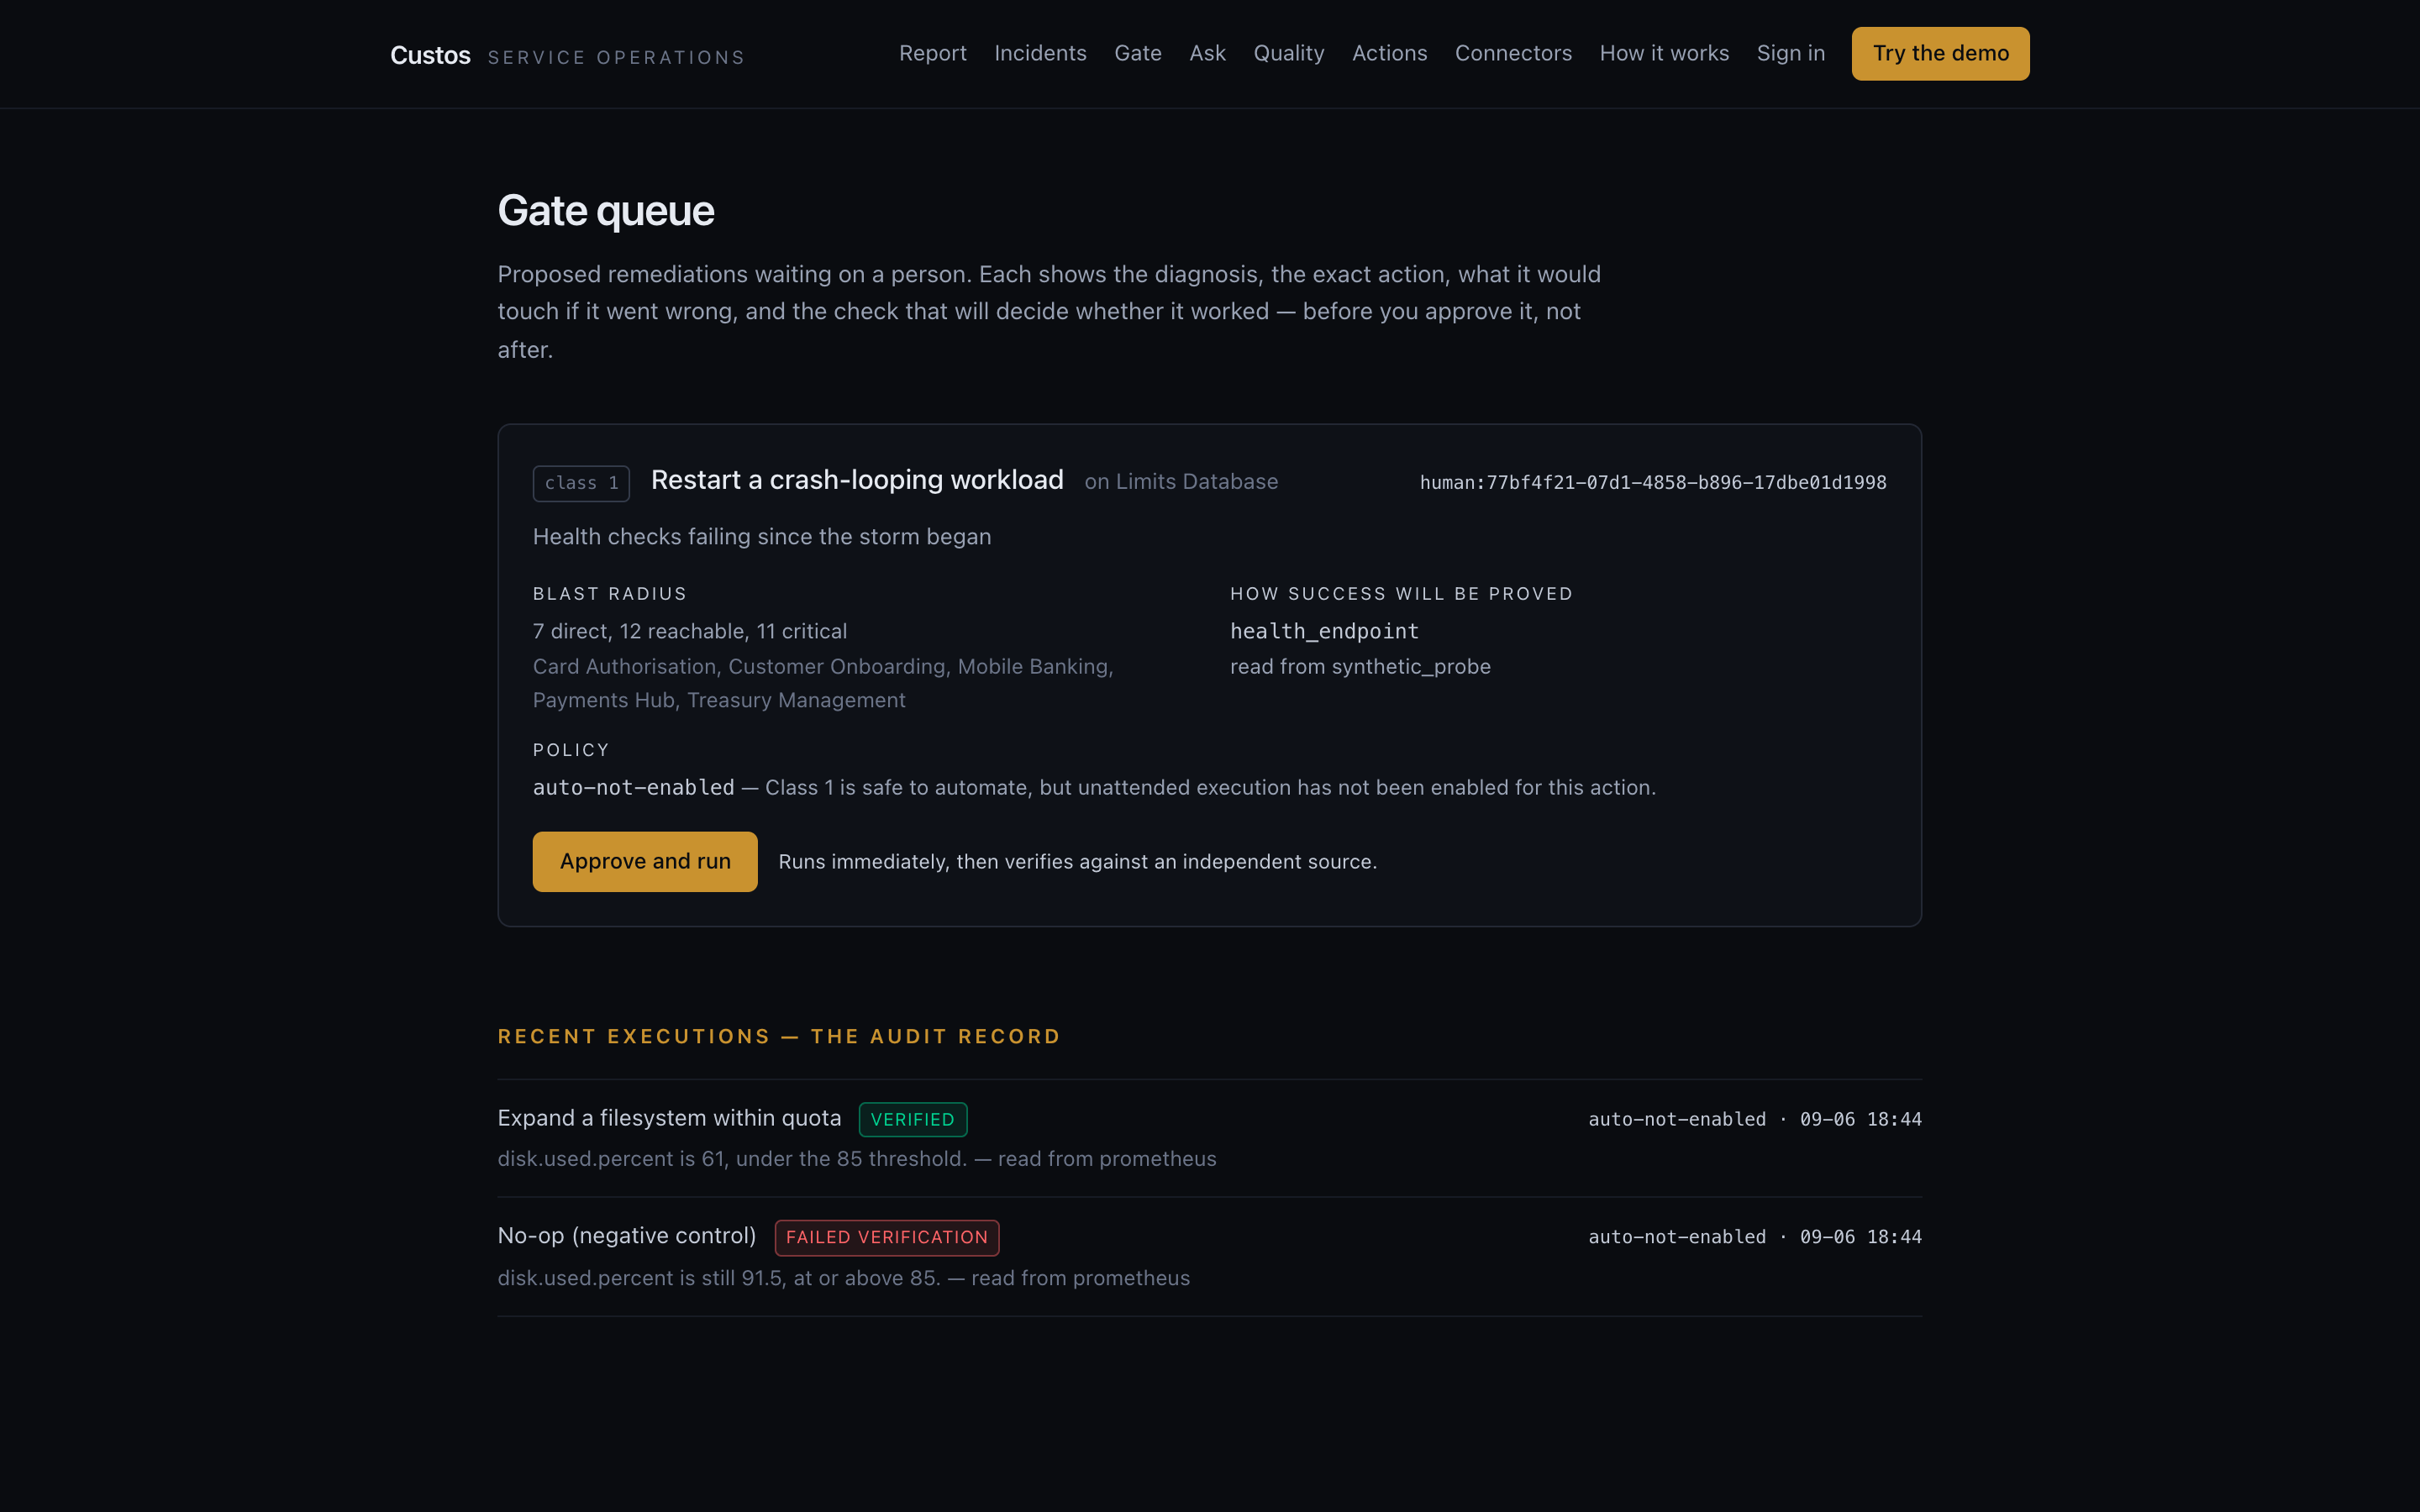
Both rows ran the same check, against the same configuration item, read from the same source. One expanded the filesystem and the disk fell to 61%. The other returned changed: true and touched nothing, so the disk is still at 90.5% — and the gate says so.
The estate ships that no-op deliberately, as a negative control. If it ever passed, “mandatory verification” would be a slogan.
Incident command
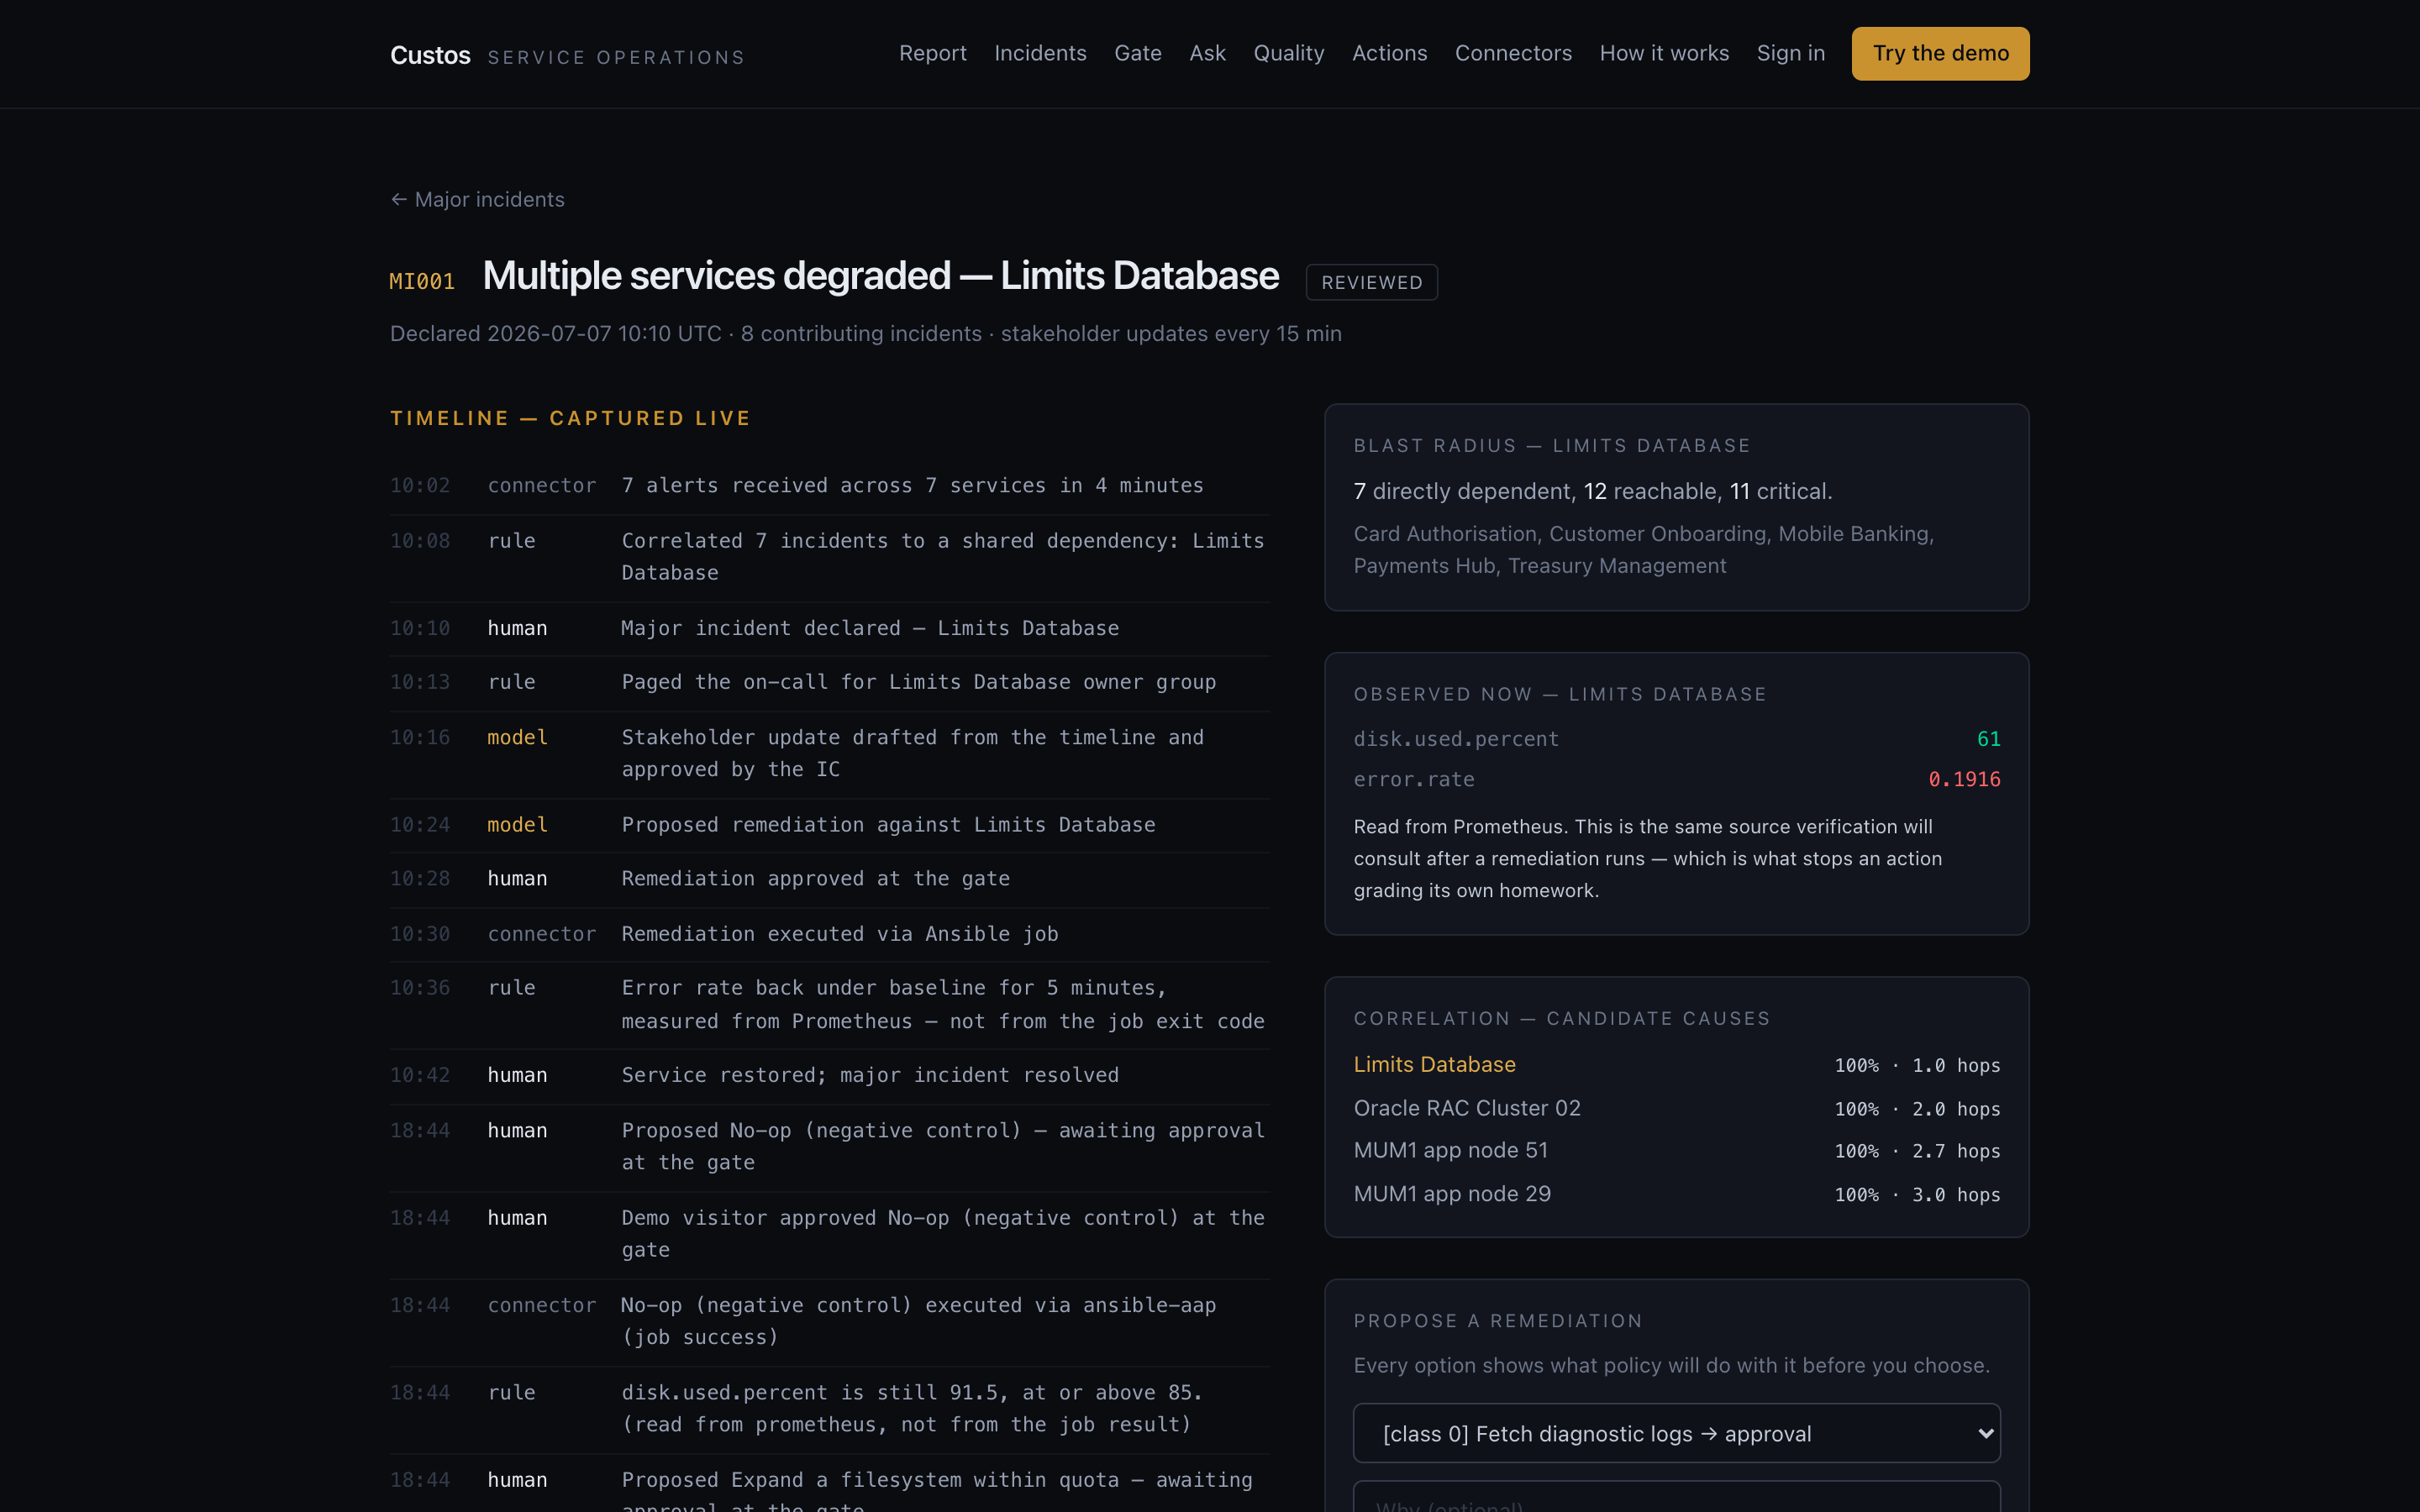
Signals, correlation, the declaration, the page, the approval, the execution and the verification — each with an actor and a timestamp, written by the thing that did it at the moment it did it.
Correlation ranks candidates by hops, not just coverage. Everything downstream of the real cause explains exactly as many incidents; without proximity you eventually blame the data centre.
Ticket quality
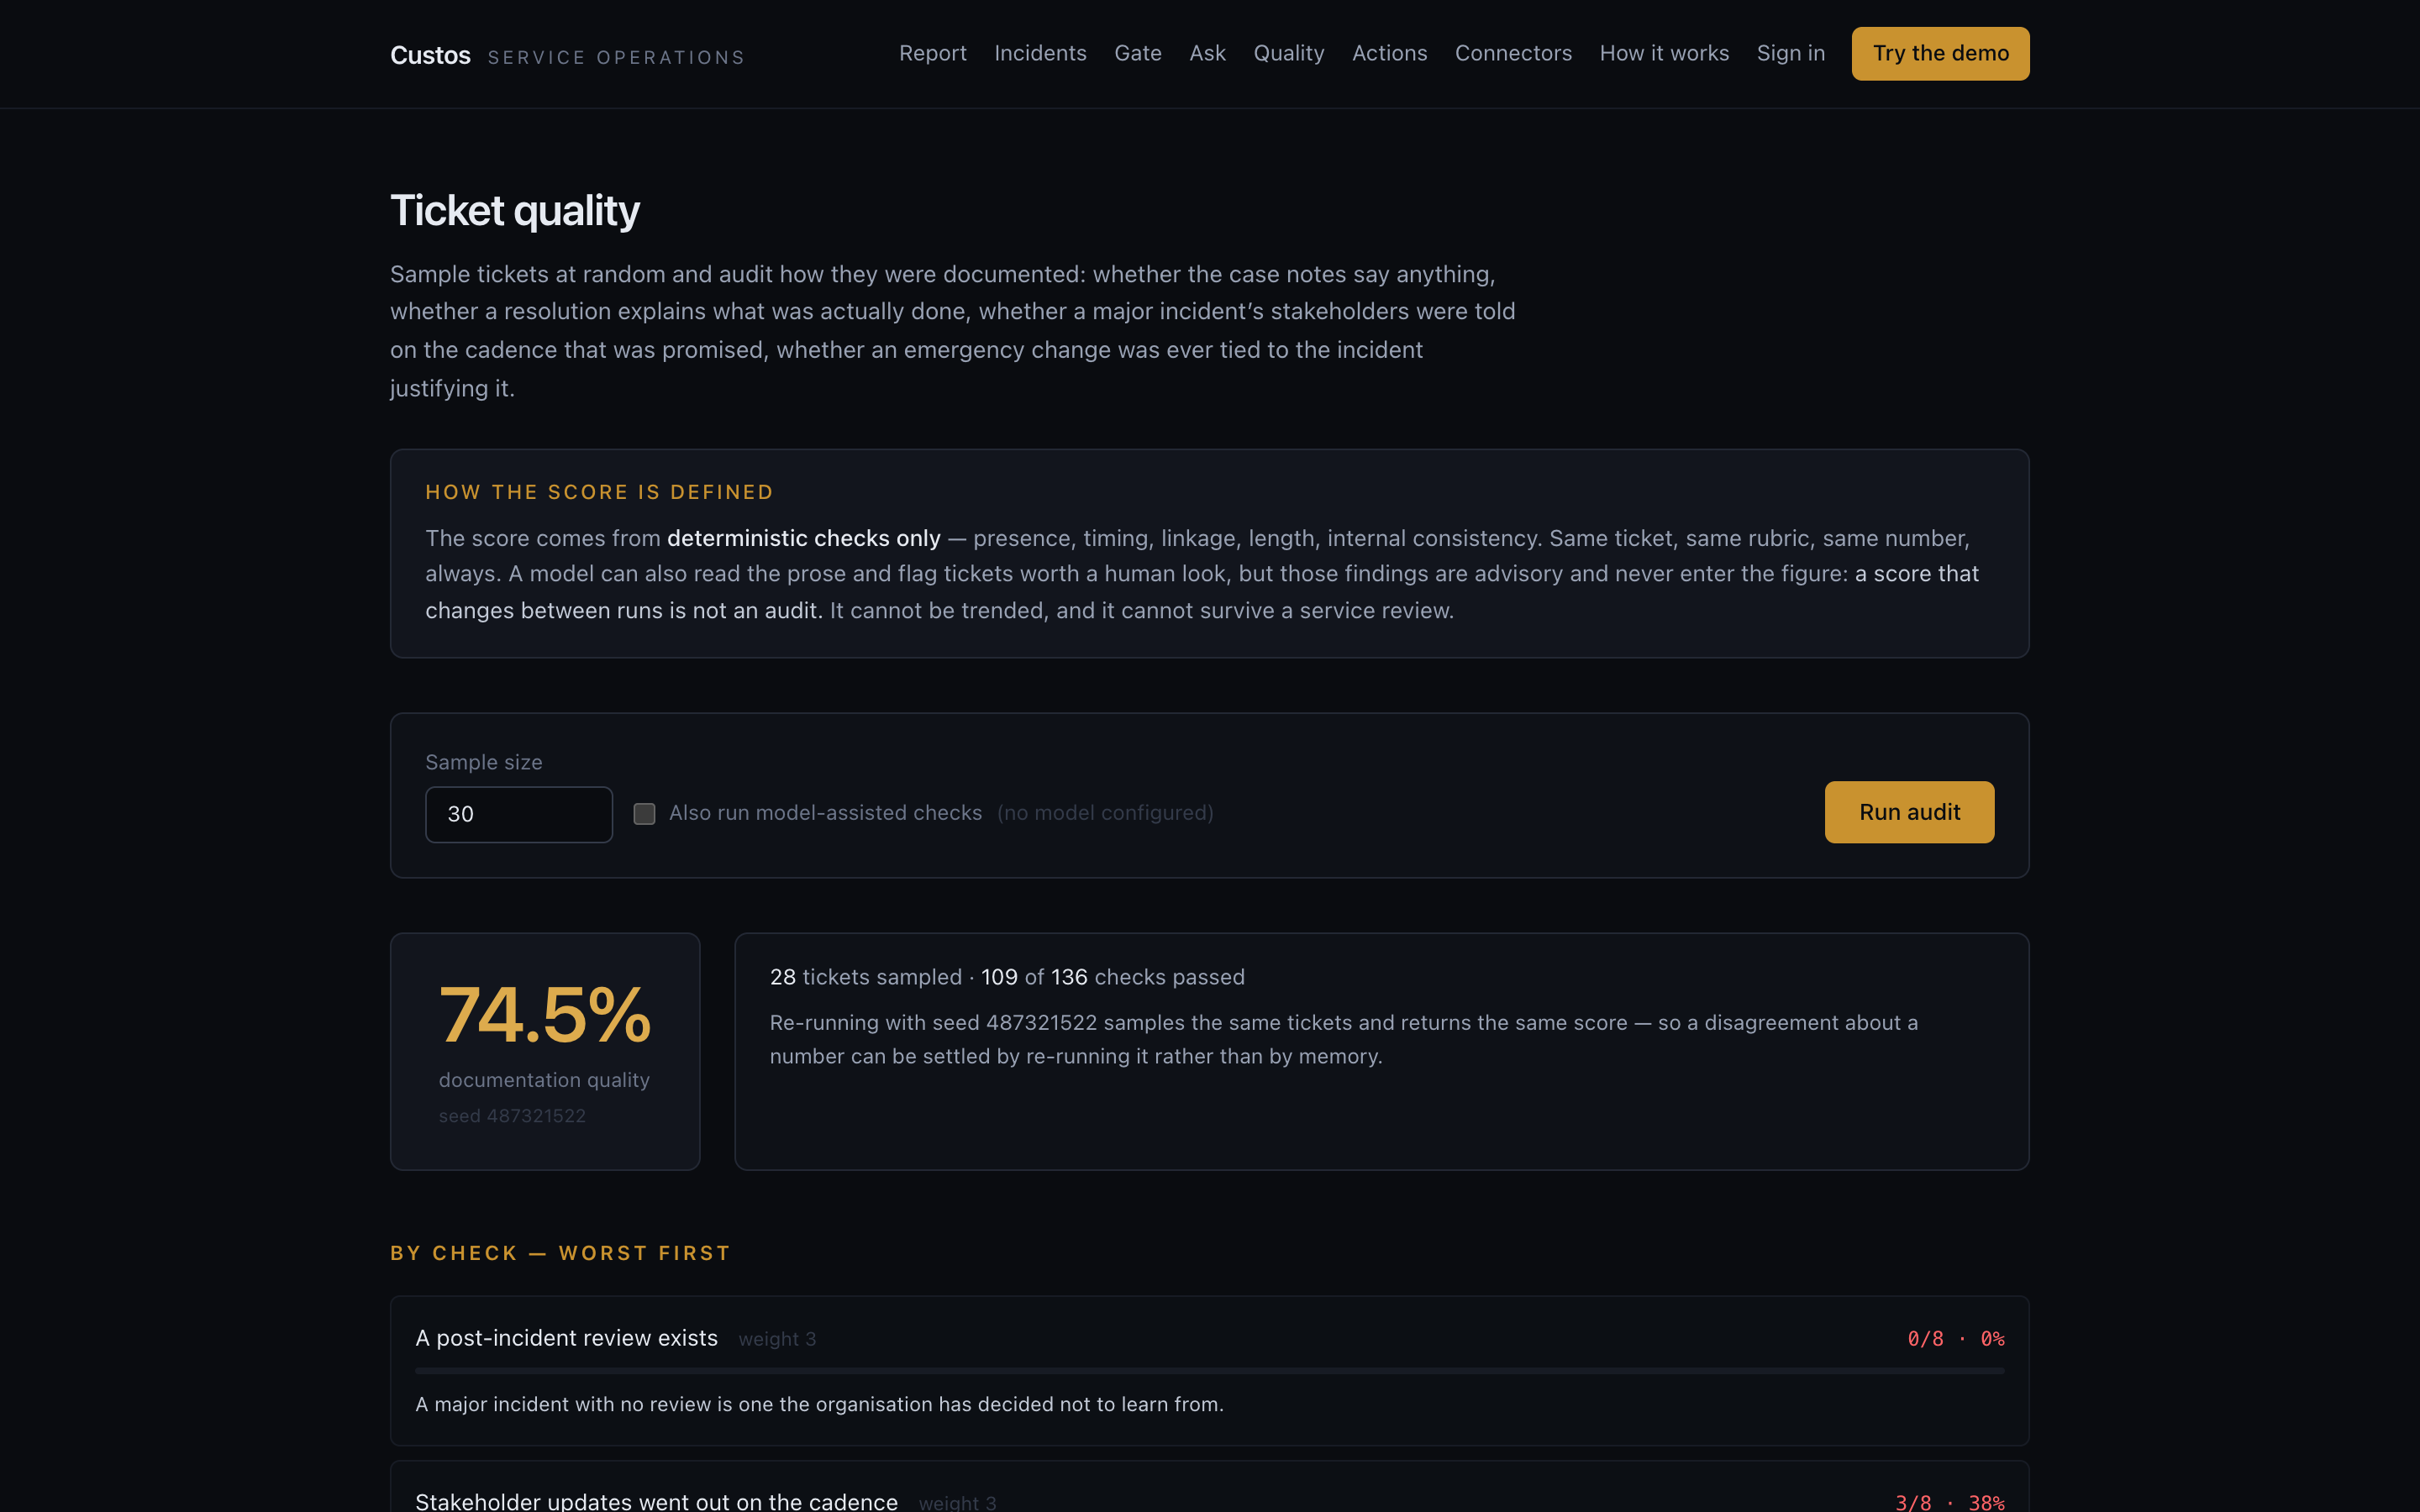
Sample tickets at random and check them against a rubric you control: resolution notes that say something, a named resolver, stakeholder updates that went out on the cadence promised, emergency changes tied to the incident justifying them.
The score is deterministic, and the seed is stored — so a disagreement about a number is settled by re-running it. A score that changes between runs is not an audit.
Ask, don’t dashboard
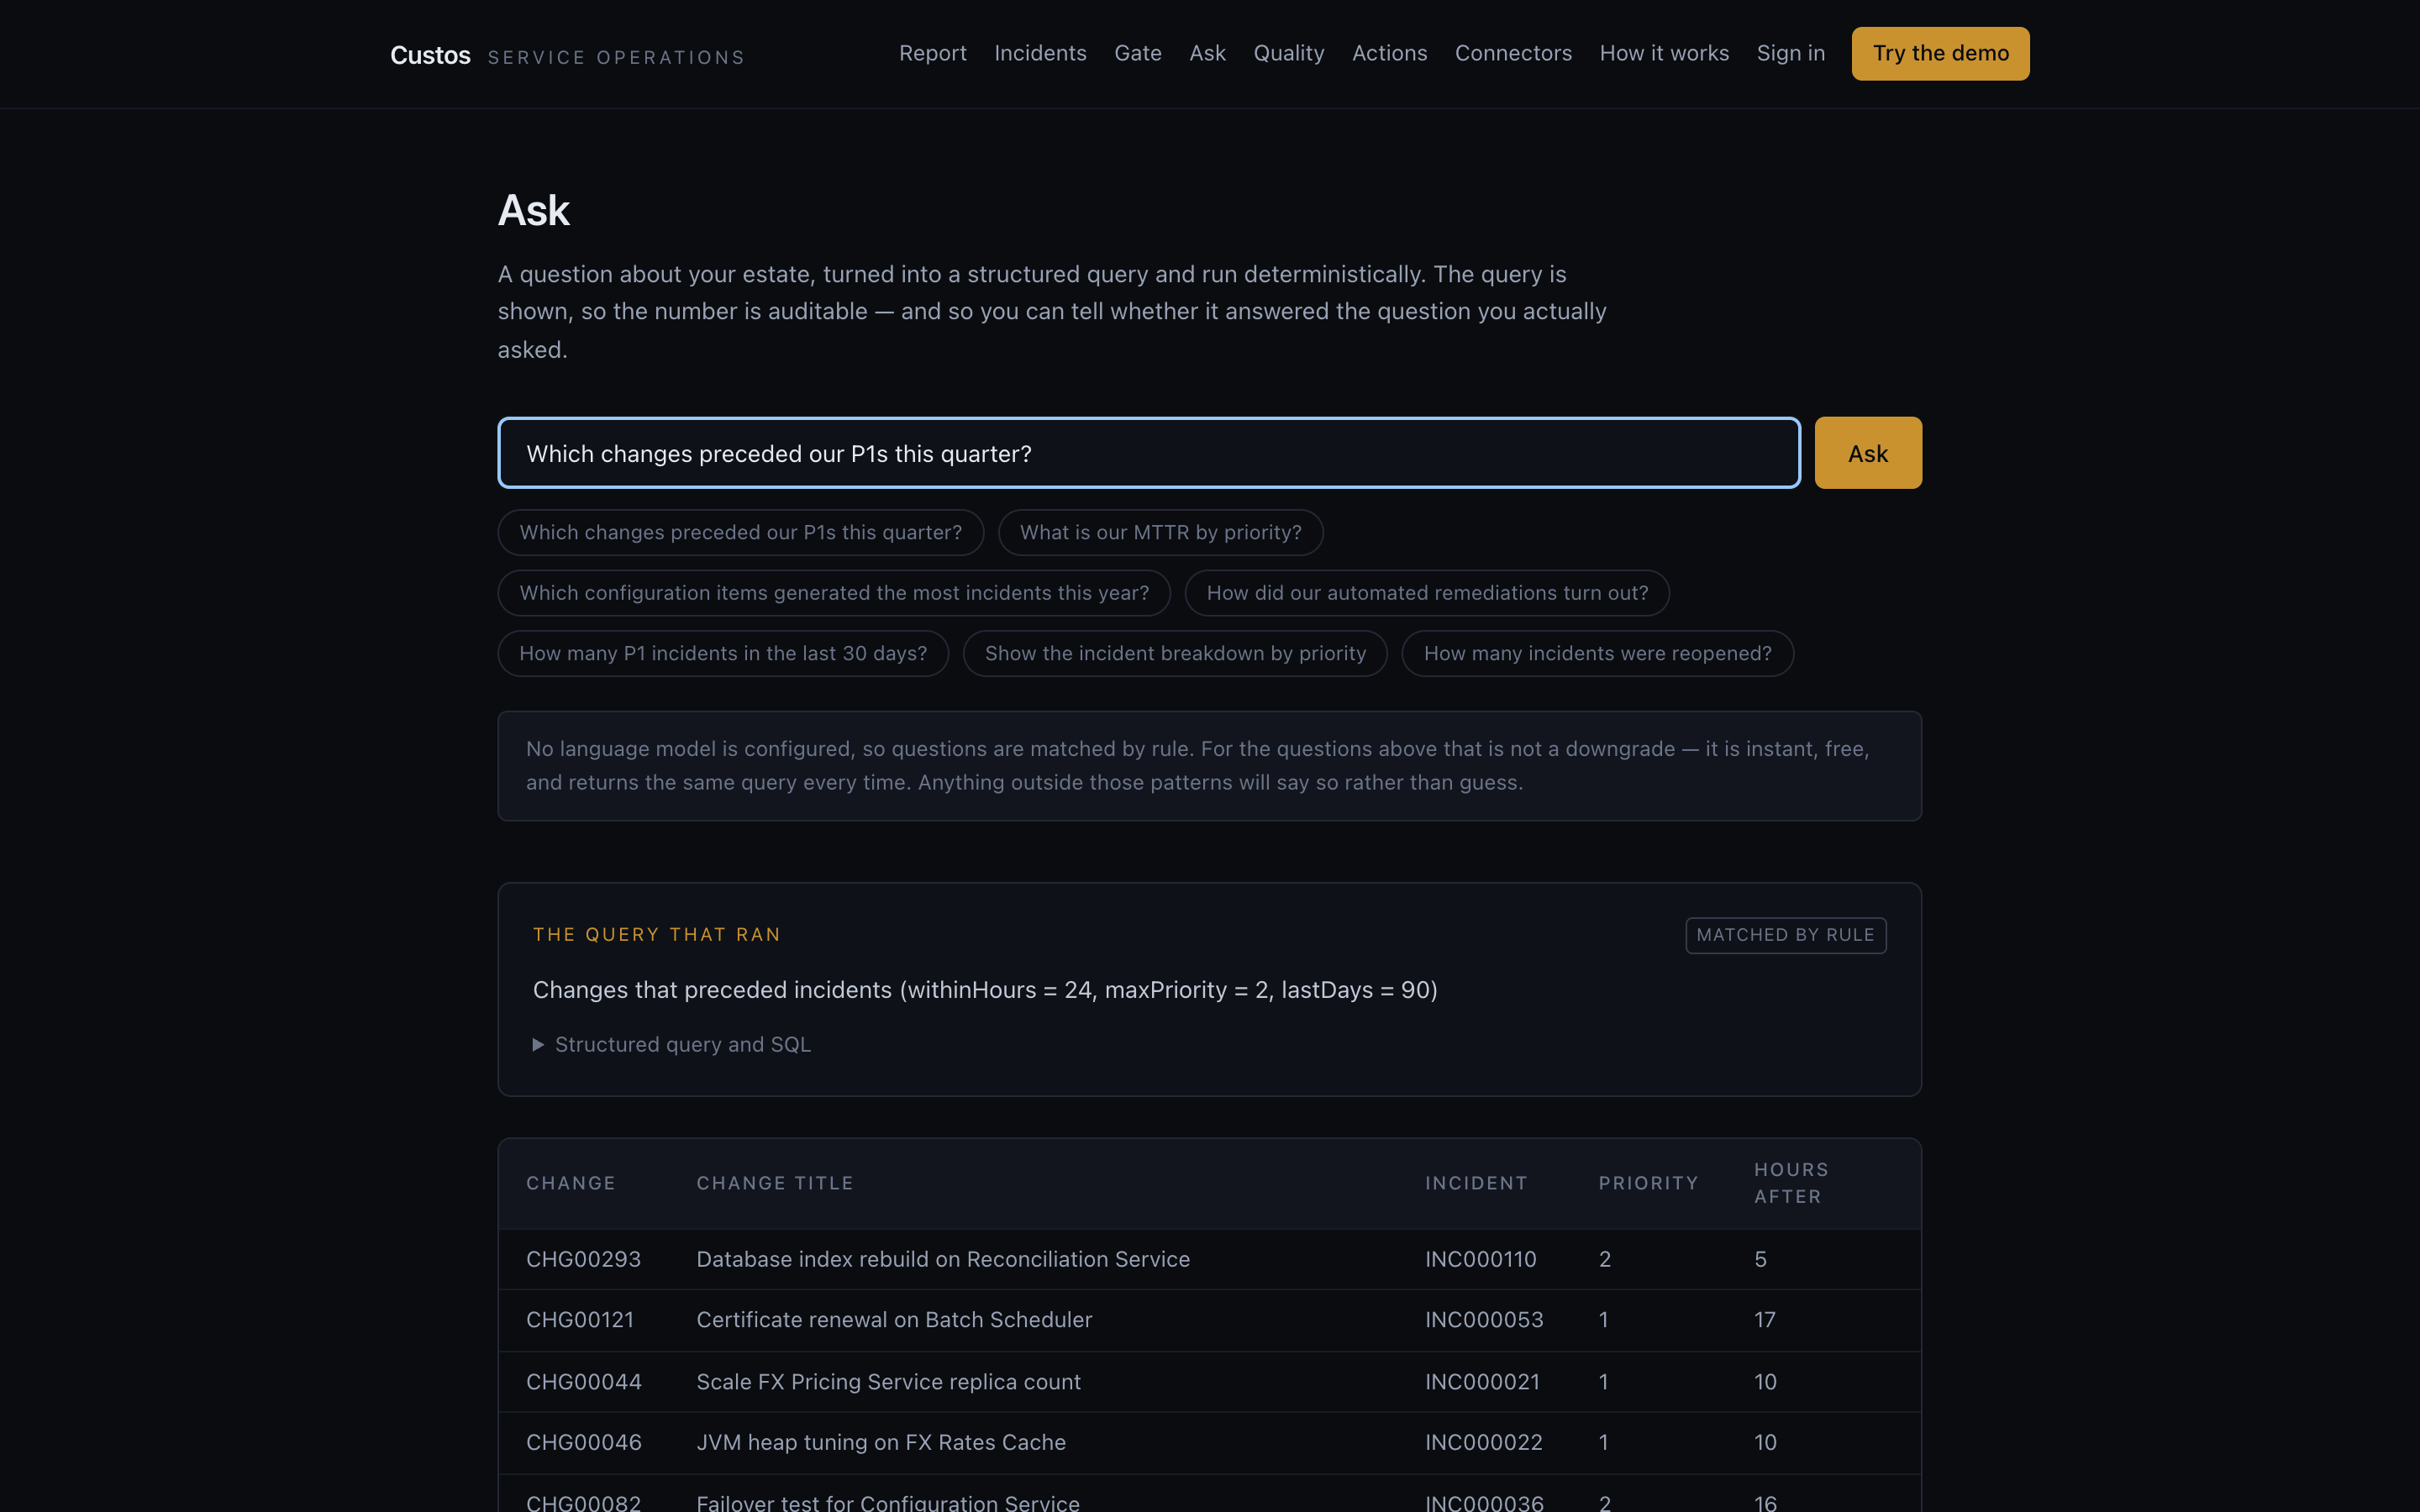
A model never writes SQL. It fills in a small typed query, which code validates against an allowlist and compiles — and if it invents a field, the question is rejected rather than quietly adjusted to fit.
Your organisation is added by the compiler as $1 of every statement. It is not a field the query language has, so no phrasing reaches another tenant.
Intake
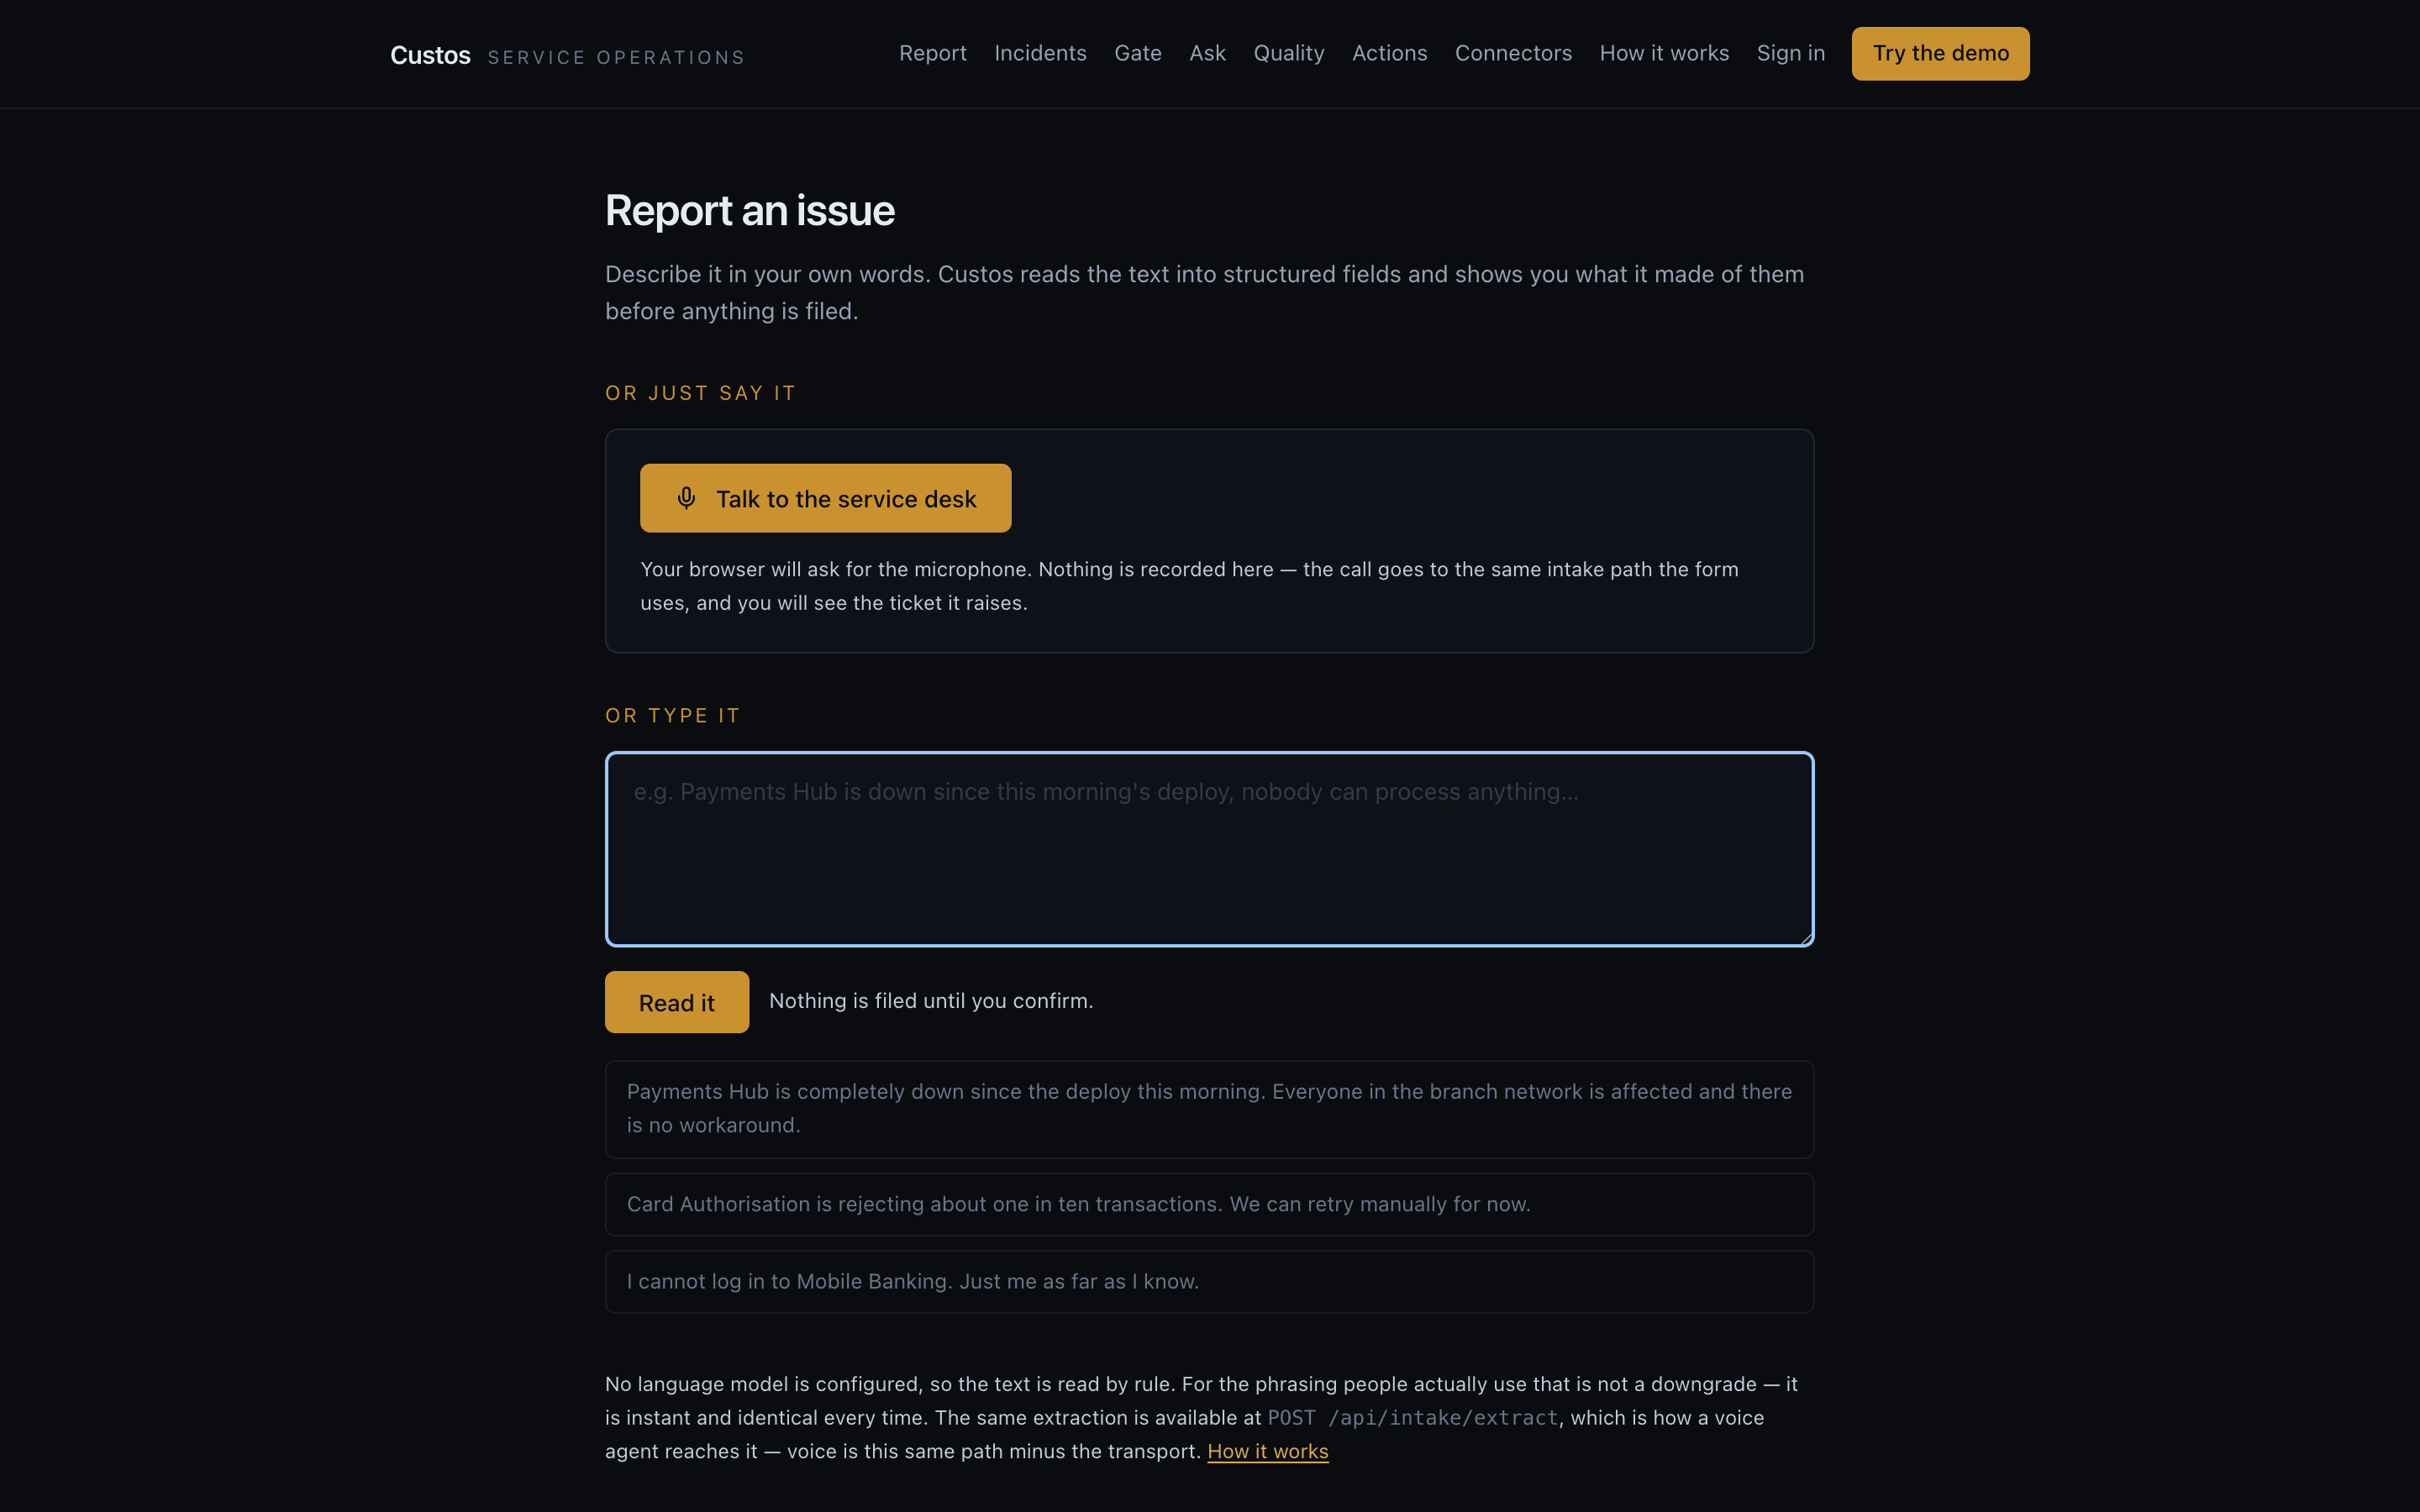
Free text becomes structured fields, checked against your own service model — an invented system is rejected, never matched to something that looks close.
Priority comes from an impact and urgency matrix, not from the wording. Writing URGENT in capitals does not move it, which is the point.
ServiceNow, Jira, Confluence, SharePoint, CyberArk, Vault, Ansible, Terraform and the observability stack you already pay for. Every connector ships a Test Connection that reports the scopes it actually found against the scopes it needs, so onboarding is something your platform team finishes in an afternoon rather than a three-week ticket exchange.
Broker mode is the default: point us at CyberArk or Vault and we persist a reference — a safe and object name, or a secret path — never the credential. We ask at execution time, use it, and discard it. Revoking us is a change in your vault, not a support ticket to us. Two fallbacks exist for estates without a vault, and we say plainly which one you are on.
Correlation, deduplication, suppression, routing, SLA computation, policy evaluation, execution and verification are deterministic — no model sits in any of those paths. A language model reads free text into structured fields, drafts a timeline into a post-incident review, and turns a question into a query that is then run by code. A saved rule returns the same answer twice, which is the whole reason for the split.
Every automated action declares, before it runs, the condition that will prove it worked — and that condition is read from a source other than the action itself. "The playbook exited zero" is not a result. "The failing health check returns 200 and the error rate has been under baseline for five minutes" is.
The demo builds you your own environment — around two hundred configuration items with a genuine dependency graph, a year of incident history, correlated storms, and changes that precede failures. Nobody wires production ServiceNow into an evaluation, so the demo environment is built as a product feature rather than a fixture.